Tag: data-structures
Teaching Computers Context: Making Meaning Mathematical with Embeddings
Posted by bsstahl on 2026-09-12 and Filed Under: development
Introduction
Imagine trying to teach a computer the subtle difference between the phrases "I need to address this issue" and "What's your address?" We recognize the intended meaning immediately because we understand the context in which the word is used. A standard text encoding, however, captures the characters in the text, not the concepts those characters represent.
This is the gap that embeddings help us bridge. An embedding represents a concept as a numerical vector, and once we have that mathematical representation, we can compare concepts, group them, and even perform arithmetic on some of their relationships. That is the real power of embeddings: they make aspects of meaning computable.
For example, consider the word "Ram." Depending on its context, it can represent several entirely different concepts:
- Computing: "I'm getting more RAM for my PC" (computer memory)
- Automotive: "I'm getting a Ram so I can pull my boat" (truck model)
- Agriculture: "I'm getting a ram and a ewe" (male sheep)
The characters alone cannot tell us which of these concepts is intended, so how can a computer distinguish among them? An embedding can represent each usage based on the ideas that surround it, giving us a mathematical way to make that distinction.
From Encoded Text to Represented Meaning
Before a machine learning model can process text, that text must be converted into numerical values. ASCII and UTF encodings represent characters as numbers, while model-specific tokenization processes assign numbers to tokens. A model can operate directly on any of these values, but there is an important limitation: the numerical order of the values does not inherently tell us anything about the relationships among the text they represent. Token 101, for example, is not necessarily more similar in meaning to token 102 than it is to token 900.
An embedding gives us an additional, learned representation. It maps a token, word, phrase, sentence, or other item to a vector, which is an ordered list of numbers that we can treat as a point in a high-dimensional space. Unlike the arbitrary relationships implied by the original numeric encoding, the position of this point can capture relationships learned from the data.
Models learn these representations through exposure to large amounts of data. The underlying idea, known as the distributional hypothesis, is that text used in similar contexts tends to have related meanings and should therefore develop related representations. The exact training process varies by model; some models create a single representation for a word, while others create representations that change based on the context. For our purposes, however, the important result is the same: concepts can be placed into a space where we can examine their relationships mathematically.
Visualizing the 'Ram' Example
Let's return to our three uses of "Ram." To visualize the idea, imagine a deliberately simplified embedding space with only three dimensions, represented as a cube. For this example, the axes correspond to the computing, automotive, and agricultural domains. Real embedding spaces usually have many more dimensions, and those dimensions generally do not have meanings that are this clear or human-readable, but this abstraction gives us a useful place to start.
- "I need to buy more RAM for my PC" would be positioned near concepts such as "Memory," "Storage," and "ROM."
- "I need to buy a Ram to haul my boat" would be positioned near "Truck," "Vehicle," and "Dodge."
- "I put the ram in the pen with the chickens" would be positioned near "Sheep," "Farm," and "Livestock."
Each sentence uses the same three letters, but its embedding occupies a different region of the space because it represents a different concept. We now have something that was not available when the text was merely encoded: a geometry that describes mathematical relationships among meanings.
Operating on Meaning
Once concepts are represented as vectors, standard mathematical operations become tools for working with meaning. What kinds of operations can we perform, and what can they tell us?
Measuring Similarity
Distance and similarity calculations tell us how close two vectors are. The embedding for the computing use of "RAM," for example, should be closer to "Memory" than to "Truck," while the automotive use should reverse that relationship. Depending on the model and the task, a system might use Euclidean distance, cosine similarity, a dot product, or another metric. These calculations are not interchangeable in every situation, but each can turn the geometric relationship between vectors into a useful numerical score.
Finding Groups
Clustering algorithms can identify regions that contain related vectors. Even without explicit labels, a collection might form distinct groups around computing, transportation, and agriculture. A classification system can then compare a new vector with known examples to determine which group it most closely resembles.
Examining Directions and Arithmetic
The differences between vectors can sometimes capture relationships between concepts, producing familiar examples such as:
king - man + woman ≈ queenparis - france + italy ≈ rometeacher - school + university ≈ professor
These analogies illustrate how a direction through the vector space can represent a conceptual relationship. They should not be treated as universal laws; whether they work depends on the model, its training data, and the specific concepts involved. Even with that limitation, they demonstrate a broader and more interesting point: embeddings support more than lookup or comparison. They give us a mathematical structure in which some conceptual relationships can be manipulated.
What This Makes Possible
These operations are the foundation for many practical systems:
- Semantic search compares the embedding of a query with the embeddings of documents or passages, allowing it to retrieve related ideas even when they use different words.
- Classification compares new text with known categories or examples, supporting scenarios such as sentiment analysis and spam detection.
- Clustering and recommendations group related items and help surface content similar to something a user already values.
- Question answering identifies passages related to a question, recognizing, for example, that "Who created C#?" and "Who is C#'s inventor?" express nearly the same intent.
Of course, putting these ideas into production introduces additional choices. Which embedding model and similarity metric should we use? Should each vector represent a word, a sentence, a paragraph, or some other chunk of content? How will the vectors be stored and searched? Multilingual and multimodal models extend the same geometric approach across languages, images, audio, and other kinds of data. The implementation details vary, but they all build on the same foundation: represent concepts as vectors, then use mathematics to work with their relationships.
Limitations and Challenges
It is important to remember that embeddings do not contain objective or complete definitions of concepts. They are learned representations shaped by a model's architecture, training data, and objectives. As a result, they can reproduce biases, miss domain-specific meanings, become less useful as language changes, or place concepts together for reasons that are difficult to interpret.
Similarity is also highly dependent on both the model and the task. Two vectors being close together means that a particular model considers them related; it does not explain the relationship or guarantee that the relationship is useful for our scenario. High-dimensional vectors can also require substantial storage and computation at scale. We should therefore evaluate embeddings against the actual task we need to perform rather than assume that geometric elegance guarantees correct results.
Conclusion
ASCII, UTF, and tokenization make text available to computation by assigning it numbers. Embeddings take us an important step further by giving learned concepts positions in a mathematical space. Within that space, the computing, automotive, and agricultural meanings of "Ram" can occupy different neighborhoods even though the original text is identical.
That shift, from encoded text to represented meaning, is what makes embeddings so powerful. Concepts become vectors, similarity becomes distance, categories become clusters, and some relationships become directions that we can explore using arithmetic. Embeddings do not give computers human understanding, but they do make useful aspects of meaning available to mathematics, and that gives us an extraordinary set of tools for building systems that operate on concepts rather than just characters.
Tags: ai algorithms data-structures embedding ml math
Identifying the Extraneous Publishing AntiPattern
Posted by bsstahl on 2022-08-08 and Filed Under: development
What do you do when a dependency of one of your components needs data, ostensibly from your component, that your component doesn't actually need itself?
Let's think about an example. Suppose our problem domain (the big black box in the drawings below) uses some data from 3 different data sources (labeled Source A, B & C in the drawings). There is also a downstream dependency that needs data from the problem domain, as well as from sources B & C. Some of the data required by the downstream dependency are not needed by, or owned by, the problem domain.
There are 2 common implementations discussed now, and 1 slightly less obvious one discussed later in this article. We could:
- Pass-through the needed values on the output from our problem domain. This is the default option in many environments.
- Force the downstream to take additional dependencies on sources B & C
Note: In the worst of these cases, the data from one or more of these sources is not needed at all in the problem domain.
Option 1 - Increase Stamp Coupling
The most common choice is for the problem domain to publish all data that it is system of record for, as well as passing-through data needed by the downstream dependencies from the other sources. Since we know that a dependency needs the data, we simply provide it as part of the output of the problem domain system.
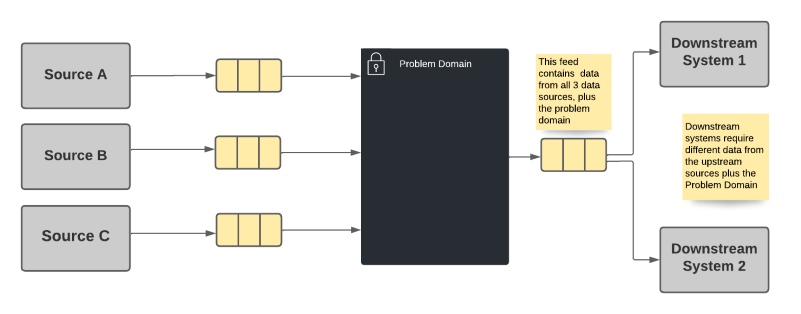
Option 1 Advantages
- The downstream systems only needs to take a dependency on a single data source.
Option 1 Disadvantages
- Violates the Single Responsibility Principle because the problem domain may need to change for reasons the system doesn't care about. This can occur if a upstream producer adds or changes data, or a downstream consumer needs additional or changed data.
- The problem domain becomes the de-facto system of record for data it doesn't own. This may cause downstream consumers to be blocked by changes important to the consumers but not the problem domain. It also means that the provenance of the data is obscured from the consumer.
- Problems incurred by upstream data sources are exposed in the problem domain rather than in the dependent systems, irrespective of where the problem occurs or whether that problem actually impacts the problem domain. That is, the owners of the system in the problem domain become the "one neck to wring" for problems with the data, regardless of whether the problem is theirs, or they even care about that data.
I refer to this option as an implementation of the Extraneous Publishing Antipattern (Thanks to John Nusz for the naming suggestion). When this antipattern is used it will eventually cause significant problems for both the problem domain and its consumers as they evolve independently and the needs of each system change. The problem domain will be stuck with both their own requirements, and the requirements of their dependencies. The dependent systems meanwhile will be stuck waiting for changes in the upstream data provider. These changes will have no priority in that system because the changes are not needed in that domain and are not cared about by that product's ownership.
The relationship between two components created by a shared data contract is known as stamp coupling. Like any form of coupling, we should attempt to minimize it as much as possible between components so that we don't create hard dependencies that reduce our agility.
Option 2 - Multiplicative Dependencies
This option requires each downstream system to take a dependency on every system of record whose data it needs, regardless of what upstream data systems may already be utilizing that data source.
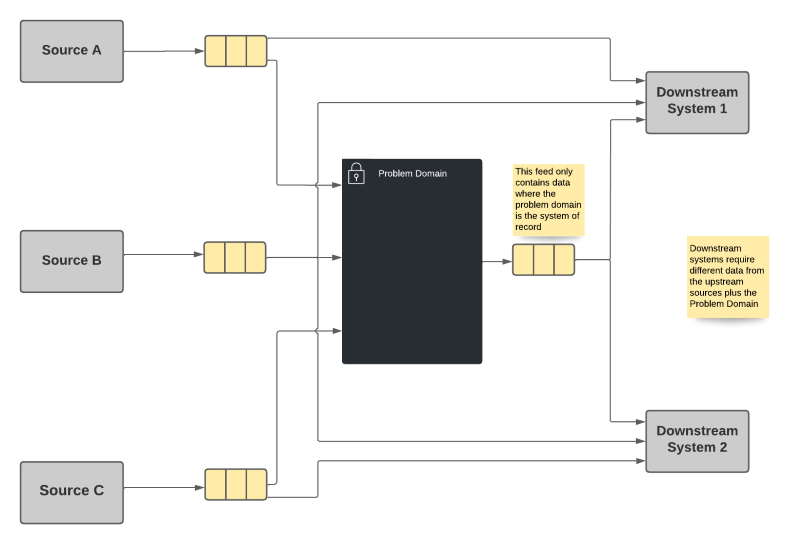
Option 2 Advantages
- Each system publishes only that information for which it is system of record, along with any necessary identifiers.
- Each dependency gets its data directly from the system of record without concern for intermediate actors.
Option 2 Disadvantages
- A combinatorial explosion of dependencies is possible since each system has to take dependencies on every system it needs data from. In some cases, this means that the primary systems will have a huge number of dependencies.
While there is nothing inherently wrong with having a large number of repeated dependencies within the broader system, it can still cause difficulties in managing the various products when the dependency graph starts to get unwieldy. We've seen similar problems in package-management and other dependency models before. However, there is a more common problem when we prematurely optimize our systems. If we optimize prematurely, we can create artifacts that we need to support forever, that create unnecessary complexity. As a result, I tend to use option 2 until the number of dependencies starts to grow. At that point, when the dependency graph starts to get out of control, we should look for another alternative.
Option 3 - Shared Aggregation Feed
Fortunately, there is a third option that may not be immediately apparent. We can get the best of both worlds, and limit the impact of the disadvantages described above, by moving the aggregation of the data to a separate system. In fact, depending on the technologies used, this aggregation may be able to be done using an infrastructure component that is a low-code solution less likely to have reliability concerns.
In this option, each system publishes only the data for which it is system of record, as in option 1 above. However, instead of every system having to take a direct dependency on all of the upstream systems, a separate component is used to create a shared feed that represents the aggregation of the data from all of the sources.
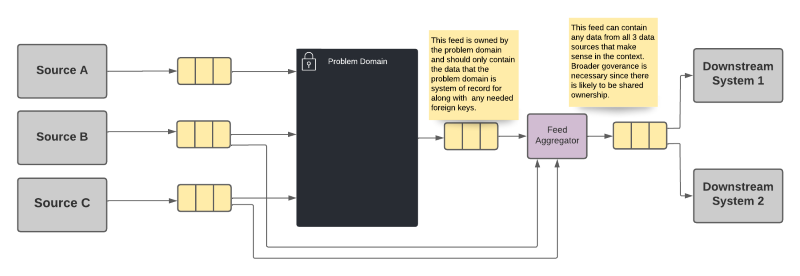
Option 3 Advantages
- Each system publishes only that information for which it is system of record, along with any necessary identifiers.
- The downstream systems only needs to take a dependency on a single data source.
- A shared ownership can be arranged for the aggregation source that does not put the burden entirely on a single domain team.
Option 3 Disadvantages
- The aggregation becomes the de-facto system of record for data it doesn't own, though that fact is anticipated and hopefully planned for. The ownership of this aggregation needs to be well-defined, potentially even shared among the teams that provide data for the aggregation. This still means though that the provenance of the data is obscured from the consumer.
- Problems incurred by upstream data sources are exposed in the aggregator rather than in the dependent systems, irrespective of where the problem occurs. That is, the owners of the aggregation system become the "one neck to wring" for problems with the data. However, as described above, that ownership can be shared among the teams that own the data sources.
It should be noted that in any case, regardless of implementation, a mechanism for correlating data across the feeds will be required. That is, the entity being described will need either a common identifier, or a way to translate the identifiers from one system to the others so that the system can match the data for the same entities appropriately.
You'll notice that the aggregation system described in this option suffers from some of the same disadvantages as the other two options. The biggest difference however is that the sole purpose of this tool is to provide this aggregation. As a result, we handle all of these drawbacks in a domain that is entirely built for this purpose. Our business services remain focused on our business problems, and we create a special domain for the purpose of this data aggregation, with development processes that serve that purpose. In other words, we avoid expanding the definition of our problem domain to include the data aggregation as well. By maintaining each component's single responsibility in this way, we have the best chance of remaining agile, and not losing velocity due to extraneous concerns like unnecessary data dependencies.
Implementation
There are a number of ways we can perform the aggregation described in option 3. Certain databases such as MongoDb and CosmosDb provide mechanisms that can be used to aggregate multiple data elements. There are also streaming data implementations which include tools for joining multiple streams, such as Apache Kafka's kSQL. In future articles, I will explore some of these methods for minimizing stamp coupling and avoiding the Extraneous Publishing AntiPattern.
